

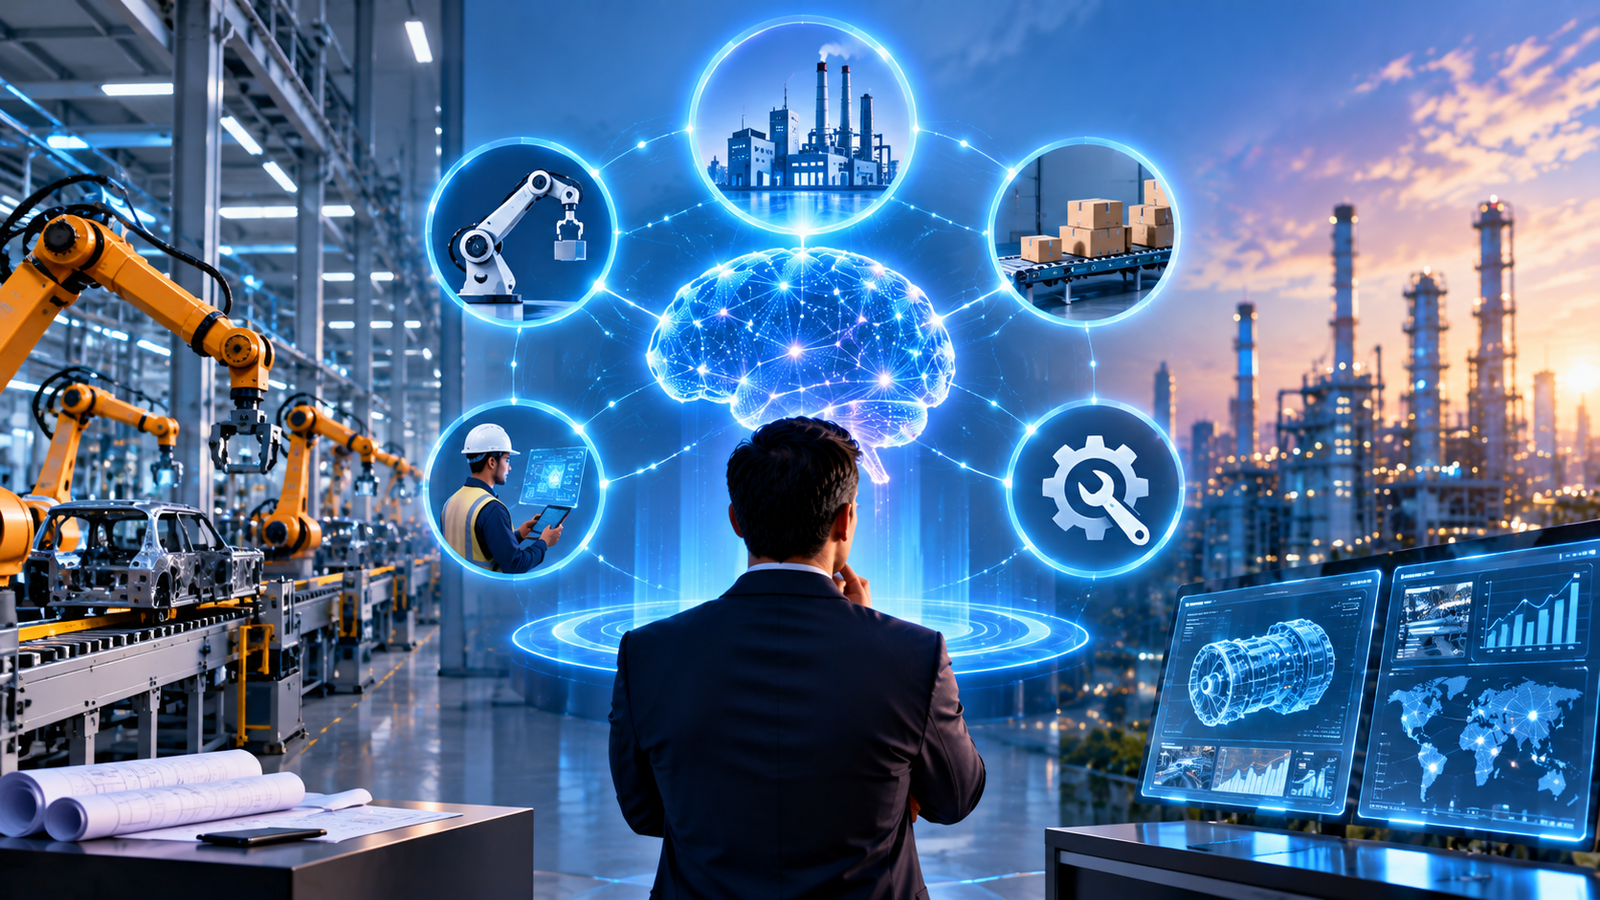
Most manufacturers have run at least one Gen AI pilot by now – a copilot for engineers, a chatbot for shop-floor queries, an experiment with generative design. Very few have anything running in production at scale. The gap isn’t ambition or budget. It’s that manufacturing Gen AI has different constraints than the office-productivity use cases most Gen AI tooling was built for, and treating them the same way is why so many pilots stall on the way to the floor.
Why Manufacturing Gen AI Is Different
Office Gen AI use cases mostly tolerate occasional errors – a slightly off email draft gets edited, a wrong meeting summary gets corrected. Shop-floor Gen AI use cases often don’t have that margin: a misread work instruction, a wrong maintenance recommendation, or a hallucinated spec on a safety-critical component can have real physical consequences. This single difference is why manufacturing Gen AI programmes need more grounding, more human-in-the-loop design, and a slower, more deliberate rollout than a typical enterprise Gen AI pilot – and why copying a generic Gen AI playbook onto the shop floor tends to underperform.
The Core Use Case Categories
1. Knowledge retrieval and technician support (RAG). Manufacturing generates enormous volumes of unstructured knowledge – maintenance manuals, engineering change orders, historical incident reports, supplier specs – that technicians currently search manually or, more often, don’t search at all and rely on tenured colleagues instead. A well-grounded RAG system that retrieves from verified, version-controlled documentation gives technicians accurate answers in seconds instead of a 20-minute manual search, or worse, a guess.
2. Engineering and design copilots. Generative design exploration, code generation for PLC and automation logic, and drafting assistance for engineering documentation are increasingly viable Gen AI applications – but only when the outputs are treated as a draft an engineer reviews, not a final artefact that ships unchecked.
3. Shop-floor conversational interfaces. Natural-language interfaces to MES, quality, and control-tower data let operators ask “why did line 3 slow down this shift” in plain language instead of navigating a reporting dashboard – but only when the underlying data is trustworthy enough to answer with, which loops back to the data foundation question that every AI initiative eventually hits.
4. Predictive and generative maintenance narratives. Combining predictive maintenance models with a generative layer that explains, in plain language, why a machine is flagged and what to check first – turning a numeric anomaly score into an actionable technician instruction.
Why Grounding Matters More Here Than Anywhere Else
A hallucinated answer in a marketing copilot is embarrassing. A hallucinated answer in a technician-facing maintenance copilot can send someone to service the wrong component, or skip a safety check the system incorrectly implied wasn’t needed. This is why manufacturing Gen AI deployments lean far more heavily on retrieval-grounded architectures (RAG against verified source documents) than on open-ended generation, and why the verification layer – citing the source document a recommendation came from – isn’t a nice-to-have, it’s frequently the difference between a technician trusting the system and ignoring it after the first bad answer.
What Good Grounding Looks Like in Practice
Grounding isn’t an abstract architectural preference – it’s a set of concrete design choices a plant manager or safety officer can actually inspect. Every technician-facing answer should cite the specific manual, revision number, and page or section it came from, so a sceptical technician can verify it against the physical binder or PDF they already trust. The retrieval index should be rebuilt automatically whenever a source document is updated, not on a manual, easily-forgotten schedule. And there should be a visible confidence signal – ideally as simple as “no matching procedure found” rather than a fabricated best guess – for the cases where the system genuinely doesn’t have grounded content to draw from.
Manufacturers that build these three things in from the start rarely have a “trust incident” that derails adoption. Manufacturers that treat them as phase-two polish frequently do, because the first ungrounded or uncited answer a technician catches becomes the story that spreads faster than any amount of subsequent accuracy improvement can undo.
How to Choose Where to Start
If your technicians spend significant time searching for documentation or asking colleagues for answers already in a manual somewhere, start with RAG-based knowledge retrieval – it’s the lowest-risk, fastest-to-value use case, because it retrieves from existing verified documents rather than generating novel content.
If your engineering teams are bottlenecked on documentation, design iteration, or code generation for automation logic, start with an engineering copilot – but plan for a review workflow from day one, not as an afterthought once errors start surfacing.
If your floor already has strong predictive maintenance in place but technicians struggle to act on the numeric outputs, a generative explanation layer on top of your existing models is a comparatively fast, high-leverage addition.
If your core floor data isn’t yet trustworthy or unified, address that first – a conversational interface or generative layer on top of unreliable data just generates confident-sounding wrong answers faster than a human would have.
What This Looks Like Across a Typical Plant
A useful way to picture the end state is to walk a single shift. A technician starts a repair and, instead of paging through a binder or calling a senior colleague, asks the RAG-based assistant for the relevant procedure – and gets an answer with a citation to the exact manual section, which they can glance at on the physical copy if they want to double-check. An engineer drafting an updated work instruction after a near-miss uses a copilot to produce a first draft from their notes, then reviews and edits it before it’s approved and – critically – before it’s fed back into the RAG index so future retrieval reflects the update. A maintenance planner reviewing an anomaly flag from the predictive model reads a plain-language explanation of what triggered it and what to check first, rather than a bare numeric score they’d have to interpret themselves. None of these interactions are dramatic. That’s the point – mature manufacturing Gen AI mostly looks like slightly faster, slightly more confident versions of tasks that were already happening, not a wholesale reinvention of how the floor operates.
The Business Case
Manufacturers deploying grounded Gen AI against well-scoped use cases report:
- 40 to 60 per cent reduction in technician time spent searching for documentation once RAG-based retrieval is deployed against verified manuals
- 20 to 35 per cent reduction in engineering documentation and drafting time with a properly reviewed copilot workflow
- 15 to 30 per cent faster mean-time-to-repair when generative explanations are layered onto existing predictive maintenance outputs
- 2 to 3 times fewer “I don’t trust this system” abandonment incidents when outputs cite verifiable source documents versus ungrounded generation
Measuring Success Beyond Accuracy
Accuracy benchmarks matter, but they’re not the metric that determines whether a manufacturing Gen AI programme actually succeeds. The more predictive signals are behavioural: how often technicians voluntarily use the system without being told to, how often they override or ignore its suggestions, and how quickly a flagged error gets corrected in the underlying documentation. A system with slightly lower benchmark accuracy but high voluntary adoption and a fast correction loop will outperform, in real operational value, a system with impressive benchmark numbers that technicians quietly stopped using after a rocky first week. Programmes that track adoption and override rates alongside accuracy catch trust erosion early, while it’s still a fixable pilot problem rather than an entrenched plant-wide scepticism.
A Phased Roadmap
Phase 1 – Foundation (Months 1-3): Identify and version-control the source documentation RAG will retrieve from; this is frequently the most time-consuming step, because manufacturing documentation is often scattered, outdated, or exists in multiple conflicting versions across plants.
Phase 2 – Pilot on Lowest-Risk Use Case (Months 3-6): Deploy RAG-based technician support in one line or plant, with explicit source citation and a feedback loop for technicians to flag wrong or outdated retrieved content.
Phase 3 – Expand and Layer (Months 6-14): Extend to engineering copilots and generative maintenance narratives, each with an explicit human review step, and roll out validated use cases across additional plants.
Phase 4 – Continuous Governance (ongoing): Monitor for documentation drift (source manuals that get updated need the retrieval index updated too), track technician trust and override rates, and treat the RAG index as a living system that needs maintenance, not a one-time deployment.
Multi-Plant Rollouts Are a Different Problem Than Single-Plant Pilots
A successful single-plant RAG pilot solves for one plant’s documentation, one plant’s terminology, and one plant’s technician trust. Rolling that same system out to a second and third plant is not simply a copy-paste exercise, because each plant often has its own document versions, its own local terminology for the same equipment, and its own history of near-misses and workarounds that never made it into the official manual. Manufacturers that treat multi-plant rollout as a scaling exercise rather than a re-validation exercise at each site tend to see accuracy quietly degrade plant by plant, without an obvious single cause – usually because the retrieval index quietly absorbed one plant’s document set as if it applied everywhere.
The manufacturers who scale well build a lightweight, repeatable “plant onboarding” checklist for the RAG system – document inventory, terminology reconciliation, and a short local trust-building pilot – rather than assuming what worked at plant one will simply transfer.
Common Mistakes
Deploying open-ended generation on safety-critical workflows. If a wrong answer has physical consequences, the system needs to be retrieval-grounded with citations, not freely generating plausible-sounding text.
Skipping the documentation cleanup step. RAG against messy, outdated, multi-version documentation just makes bad information easier to retrieve faster – cleanup isn’t optional overhead, it’s the actual foundation of the system’s value.
Treating this as an IT project rather than a floor adoption project. Technicians who don’t trust the system after one bad early answer rarely give it a second chance – early pilots need to be scoped conservatively enough to build trust before expanding scope.
Who Should Own This Programme
Manufacturing Gen AI programmes cut across IT, engineering, and plant operations, and the accountability question matters as much as the technical architecture. Programmes led solely by IT tend to underweight shop-floor trust dynamics and over-invest in platform capability the floor doesn’t actually need yet. Programmes led solely by plant operations tend to underweight the documentation governance and data lineage work that keeps the system accurate over time. The manufacturers who scale successfully usually appoint a joint owner – often a plant engineering lead paired with an IT or data lead – accountable for both the technical grounding and the floor-level trust the system needs to survive contact with real technicians.
A Note on Cost and Scale
Manufacturing Gen AI programmes are frequently priced and budgeted as if they were a single project, when in practice they’re closer to an ongoing capability with a meaningful upfront foundation cost and a smaller, recurring maintenance cost thereafter. The upfront cost is dominated by documentation cleanup and indexing – often 50 to 60 per cent of total first-year spend – which is also the part of the programme least visible to executive sponsors who mainly see the technician-facing interface. Budgeting for this accurately upfront, rather than underestimating it to make an initial business case look leaner, is one of the more reliable predictors of whether a programme survives its first budget review once the “unglamorous” documentation phase runs longer than the pitch deck implied it would.
Why Enterprises Choose SMI TECHSOLUTIONS for Manufacturing Gen AI
SMI TECHSOLUTIONS builds manufacturing Gen AI on grounded, retrieval-based architectures by default – not because it’s more impressive, but because it’s what actually earns technician trust on the floor. Our Gen AI and manufacturing teams work together to clean and structure the documentation foundation before deploying anything customer-facing, and we scope pilots conservatively enough to prove trust before scaling – because a manufacturing Gen AI programme that loses technician confidence in week one rarely recovers it.
Related Reading
- Why Manufacturing Gen AI Pilots Never Make It to the Shop Floor
- RAG vs Copilot for Manufacturing: Which Fits Your Use Case?
Related Services
- Generative AI Services
- RAG (Knowledge-Based)
- Copilot
- Manufacturing
- Data Engineering & BI Services
- AI-Centric Bespoke Development
Ready to Scope Your Manufacturing Gen AI Roadmap?
Ready to scope your manufacturing Gen AI roadmap? Talk to our team to discuss your use case, data foundation, and rollout requirements.